What You Need
- Hardware: Any computer with a web browser
- Software: An AWS account signed in as an admin identity (see the IAM guide), an S3 bucket for the upload example. Lambda's monthly free allowance applies to every account, but other services used here follow your account's Free Tier plan, which changed for accounts created on or after July 15, 2025. Python 3 and
ziplocally for the deployment-package section; AWS CLI v2 optional. - Time: 30-60 minutes
- Free allowance: 1 million requests and 400,000 GB-seconds of compute per month.
- Timeout: 3 seconds by default, 900 seconds (15 minutes) maximum.
- Memory: 128 MB to 10,240 MB; CPU scales with it.
- Deployment package: 50 MB zipped for direct upload, 250 MB unzipped including layers; container images up to 10 GB.
- No long-lived inbound connections: each invocation handles one event and returns.
💡 Check package size early: workloads that bundle a headless browser or large native libraries can exceed the 250 MB unzipped limit before you've written much code. If that happens, a container image (up to 10 GB) or a container service such as Fargate is the usual way out.
When Lambda Makes Sense
A lot of backend work has the same shape: wait for something, do a thing, stop. That shape fits Lambda well.
File lands in S3? Resize it. Row appears in DynamoDB? Notify somebody. API call comes in through API Gateway? Return JSON. Scheduled job needs to run at 2 AM? EventBridge triggers it. Each one is its own isolated function. Each one scales to zero when nobody is using it, and an idle function costs nothing.
The 15-minute execution limit is the main wall. If your task genuinely needs to run longer than that, Lambda is the wrong tool. Often the limit pushes you to split big jobs into smaller chunks and fan them out with SQS, which also makes retries and partial failures easier to handle. For long-running daemons, see Launch Your First EC2 Instance instead.
Your First Function (Console)
Fastest way to get something running. Skip the CLI for now and go straight to the console:
- Go to the Lambda Console
- Click Create function
- Select Author from scratch
- Name it something like
my-first-function - Runtime: Python 3.14 (or Node.js 24 if you prefer)
- Leave everything else at defaults. Lambda creates an execution role that can write logs to CloudWatch
- Click Create function
Runtime versions: as of October 2026, the Lambda runtimes page lists Python 3.14 and Node.js 24 as the newest generally available runtimes for those languages (identifiers python3.14 and nodejs24.x). Python 3.15 and Node.js 26 are in public preview, which AWS says is not for production workloads. Python 3.12 and 3.13 are still supported, with deprecation dates listed in the same table. The code below runs unchanged on any of them.
You'll see a code editor with a starter function similar to this:
import json

def lambda_handler(event, context):
    return {
        'statusCode': 200,
        'body': json.dumps('Hello from Lambda!')
    }
Bare minimum. Two arguments come in, one response goes out. Here's what each piece does:
- lambda_handler: the entry point. The handler setting (
lambda_function.lambda_handlerby default) tells Lambda which file and function to call. You can change it in the runtime settings, but there's rarely a reason to. - event: whatever triggered the function sends its data here. HTTP body, S3 file metadata, SQS message: it all arrives as a dict.
- context: runtime info. Mostly useful for checking how much execution time is left via
context.get_remaining_time_in_millis(). - return: goes back to the caller. For API Gateway integrations, you need statusCode and body. For asynchronous triggers such as S3, the return value is discarded.
Test It
- Click Test
- Create a new test event, name it
test-event - Leave the default JSON
- Click Save, then Test again
The console shows the execution result. On success, the response is the dict your handler returned, serialized as JSON: a statusCode of 200 and a body containing the JSON-encoded string "Hello from Lambda!". Below it are the function's log output and a summary with the duration, billed duration and memory used.
A Real Example: File Upload Processor
This is closer to what you'd actually deploy. A file hits S3, Lambda wakes up, logs what arrived:
import json
import urllib.parse

def lambda_handler(event, context):
    processed = []
    # One notification can carry more than one record
    for record in event.get('Records', []):
        bucket = record['s3']['bucket']['name']
        key = urllib.parse.unquote_plus(record['s3']['object']['key'], encoding='utf-8')
        size = record['s3']['object'].get('size', 0)

        print(f"New object: s3://{bucket}/{key} ({size} bytes)")
        processed.append(key)

    return {
        'statusCode': 200,
        'body': json.dumps({'processed': processed})
    }
Object keys arrive URL-encoded in the event (a space becomes +), which is why the key goes through unquote_plus before you use it.
Connect It to S3
- In your Lambda function, go to Configuration → Triggers
- Click Add trigger
- Select S3
- Choose your bucket
- Event type: All object create events
- Acknowledge the recursive-invocation warning and click Add
That warning matters: if the function writes its output back into the same bucket (or the same prefix) that triggers it, every write triggers another invocation. Write results to a different bucket, or limit the trigger to a prefix such as uploads/ and write to processed/. Lambda's recursive loop detection stops a loop through S3 after about 16 invocations in the same chain, but only when the function writes with a supported AWS SDK version, so treat it as a backstop rather than the fix.
The bucket has to be in the same Region as the function; buckets in other Regions don't appear in the trigger's list. To test, upload a file (to the prefix, if you set one). S3 delivers the event to Lambda asynchronously, usually within seconds:
echo "hello" > test.txt
aws s3 cp test.txt s3://your-bucket/uploads/test.txt
Check the Logs
Every print() in your function ends up in CloudWatch Logs, as long as the execution role allows it (the default role does). No logging library needed:
- Go to CloudWatch → Log groups (or Monitor → View CloudWatch logs from the function page)
- Find
/aws/lambda/my-first-function - Click into the latest log stream
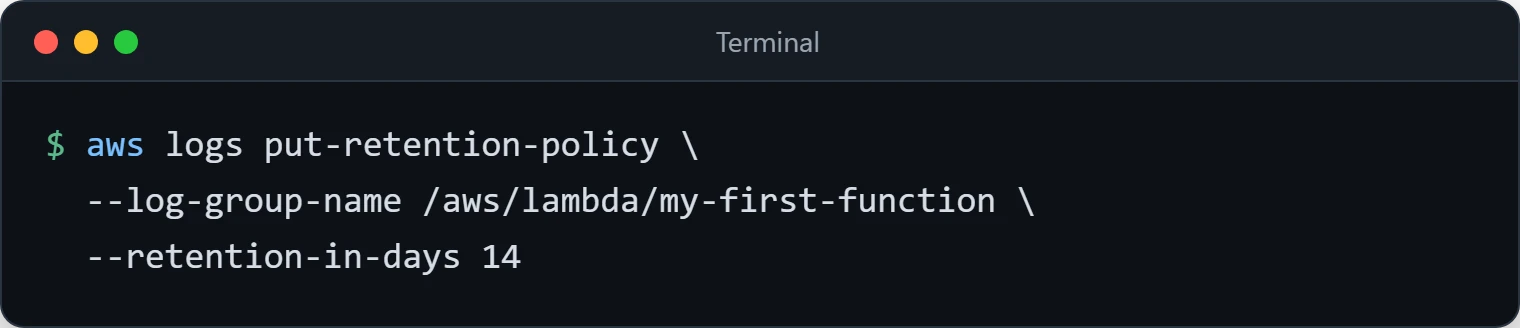
Your print output shows up between a START line and a REPORT line for each invocation. The REPORT line has the duration, billed duration, configured memory and maximum memory used, plus an Init Duration on cold starts. This is how you debug Lambda: there is no server to SSH into. See Sending Lambda function logs to CloudWatch Logs. For the test upload you should see a line like New object: s3://your-bucket/uploads/test.txt (6 bytes).
CloudWatch Logs keeps log events indefinitely unless you set a retention period, and stored logs are billed. Set one now:
aws logs put-retention-policy \
  --log-group-name /aws/lambda/my-first-function \
  --retention-in-days 14
Using Environment Variables
Configuration such as table names, URLs and feature flags belongs in environment variables, not in the source code:
- In your Lambda, go to Configuration → Environment variables
- Click Edit, then Add environment variable
- Add key
API_KEYwith your value - Save
Then read it in your handler like any other env var:
import os

api_key = os.environ['API_KEY']const apiKey = process.env.API_KEY;Environment variables are encrypted at rest, but anyone who can view the function configuration can read them, and all variables together are limited to 4 KB. For real secrets, store them in AWS Secrets Manager or Systems Manager Parameter Store and grant the execution role permission to read that one secret.
Adding Dependencies
The Python runtimes include the AWS SDK (boto3) and the standard library. Anything beyond that, you have two paths:
Option 1: Lambda Layers
Layers let you share packages across multiple functions. AWS publishes some, such as the AWS SDK for pandas:
- In your Lambda, go to Layers
- Click Add a layer
- Choose AWS layers
- Select the one matching your runtime and architecture, for example
AWSSDKPandas-Python314for Python 3.14 on x86_64
Pandas is then importable in the function without bundling it. A function can use up to 5 layers, and the 250 MB unzipped limit counts the layers too.
Option 2: Deployment Package
When the library you need isn't in a pre-built layer, you bundle everything into a zip:
# Build in a virtual environment so pip doesn't touch the system Python
python3 -m venv ~/lambda-build-venv
. ~/lambda-build-venv/bin/activate

mkdir my-lambda-package && cd my-lambda-package

# Install dependencies into this directory
pip install --target . requests

# The handler file goes at the top level of the package
cat > lambda_function.py <<'EOF'
import requests

def lambda_handler(event, context):
    response = requests.get("https://checkip.amazonaws.com", timeout=5)
    return {"ip": response.text.strip()}
EOF

# Zip the directory's contents, not the directory itself
zip -r ../deployment-package.zip .

# Replace the function's code with the package
aws lambda update-function-code --function-name my-first-function \
  --zip-file fileb://../deployment-package.zip
This replaces the S3 handler from earlier, so use a second function if you want to keep both. Run Test in the console afterwards: the result should be a JSON object with your function's outbound IP address. Zips over 50 MB have to go through S3 instead of a direct upload.
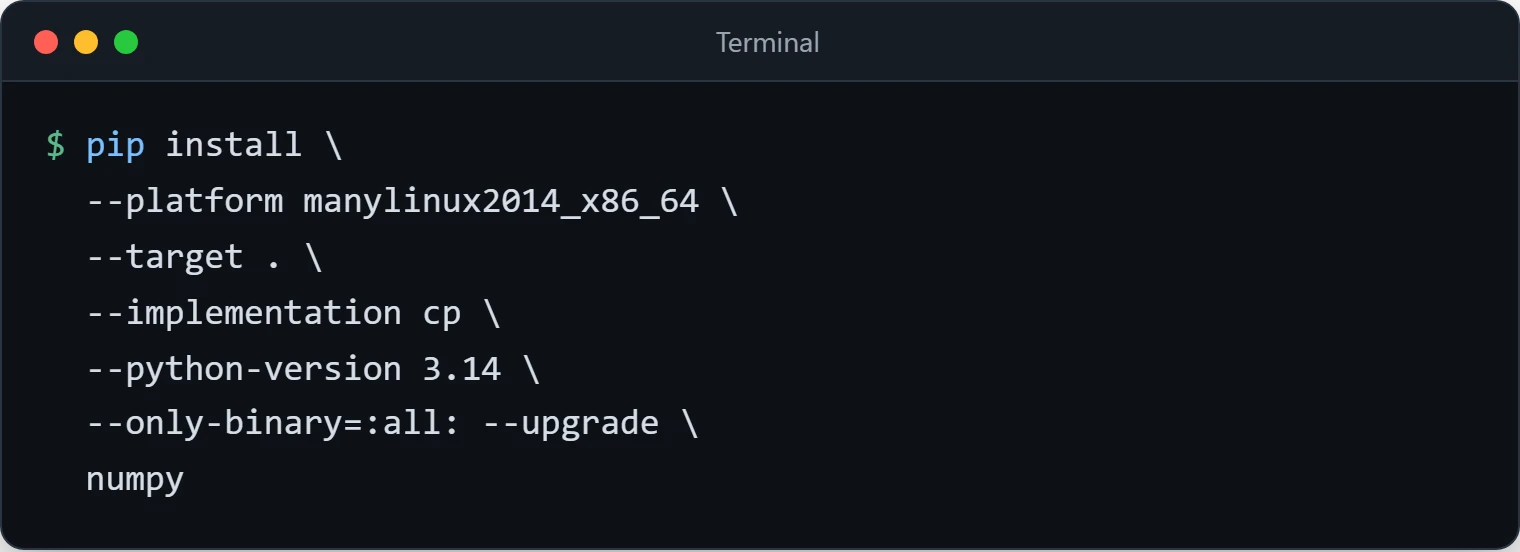
Pure-Python packages like requests work this way from any OS. Packages with compiled parts (NumPy, Pandas, cryptography and many others) need wheels built for Linux and the function's architecture. The Python deployment package guide uses pip's --platform option for that; for an x86_64 function on Python 3.14:
pip install \
  --platform manylinux2014_x86_64 \
  --target . \
  --implementation cp \
  --python-version 3.14 \
  --only-binary=:all: --upgrade \
  numpy
For an arm64 function, use manylinux2014_aarch64. Packages that only ship source distributions have to be built on Amazon Linux, for example on an EC2 instance or in a container.
Scheduled Execution (Like Cron)
Scheduled jobs are one of the simplest Lambda use cases, and they remove the need for a server whose only job is running cron:
- In your Lambda, go to Configuration → Triggers
- Click Add trigger
- Select EventBridge (CloudWatch Events)
- Create a new rule
- Rule type: Schedule expression
- Enter a cron expression or rate:
rate(1 hour)orcron(0 9 * * ? *)for 9 AM daily
Schedule expressions on EventBridge rules are evaluated in UTC, so cron(0 9 * * ? *) is 09:00 UTC. Typical jobs: nightly cleanup, daily exports, and simple uptime checks that call a few URLs every few minutes. For time-zone-aware or one-off schedules, EventBridge Scheduler is the newer option.
A scheduled event looks nothing like an S3 event: it has "source": "aws.events" and "detail-type": "Scheduled Event" and no Records list. The S3 handler above skips it because it loops over event.get('Records', []), but a handler that indexes event['Records'][0] fails with KeyError: 'Records'. Give each trigger its own function, or branch on event.get('source'). To confirm the schedule works, use rate(5 minutes) while testing and watch for a new START/REPORT pair in the log group, then change it to the real schedule.
Permissions (IAM Roles)
Every Lambda runs under an IAM role, its execution role. The default one created with the function can write to CloudWatch Logs and nothing else. You have to explicitly grant access to every other AWS service.
Say your function needs to read from S3:
- Go to Configuration → Permissions
- Click on the role name (opens IAM console)
- Click Add permissions → Attach policies
- Search for
AmazonS3ReadOnlyAccess, or better, create a policy limited to the one bucket - Attach
Your function can now read from S3. Resist the urge to attach AdministratorAccess and "fix it later": a function with admin rights turns any bug or injected input into full control of the account. Secure Your AWS Account with IAM shows how to write a bucket-scoped policy and test it with the policy simulator.
Memory and Timeout
Two knobs that control most of a function's behaviour and cost:
- Memory: 128 MB (the default) to 10,240 MB. CPU is allocated in proportion to memory; at 1,769 MB a function has the equivalent of one vCPU. AWS recommends 128 MB only for simple functions that transform and route events. Functions that import larger libraries or talk to S3 usually run faster with more, and because you're billed per GB-second, a faster run at higher memory can cost about the same.
- Timeout: 3 seconds by default, up to 900 seconds. A function that calls an external API or reads from S3 can exceed 3 seconds occasionally; when it does, Lambda stops it and logs a timeout.
Both live under Configuration → General configuration.
Set the timeout comfortably above the function's normal duration (check the REPORT lines in the logs), and size memory by measuring rather than guessing. AWS's memory guide points to the open-source AWS Lambda Power Tuning tool for that.
Cold Starts
A cold start happens when Lambda has to create a new execution environment: download your code, start the runtime and run your initialization code before the handler. Later invocations reuse the warm environment. How long it takes depends on runtime, package size and what your code does at import time; the Init Duration field in the REPORT log line shows it for your function. Background jobs, scheduled tasks and webhook processors rarely care. User-facing API endpoints are where it shows.
Cold starts also cost a little. Since August 1, 2025, Lambda bills the initialization (INIT) phase for on-demand invocations of .zip functions on managed runtimes, as it already did for container images, custom runtimes and provisioned concurrency (AWS announcement). Heavy work at import time now shows up in the bill as well as in latency.
If cold starts actually matter in your case:
- Provisioned Concurrency: keeps a configured number of environments initialized. It's billed for as long as it's enabled, and the Lambda free tier doesn't apply to functions that use it (see Configuring provisioned concurrency).
- Smaller deployment packages and lazy imports: less code to load and less work at import time means shorter initialization. Drop unused dependencies.
- More memory: more CPU also speeds up initialization.
- Compiled languages: Go and Rust run on Lambda's OS-only runtimes and tend to initialize quickly, if rewriting is an option.
Calling Lambda from Other AWS Services
Most AWS event sources connect to Lambda through configuration alone:
- API Gateway: REST and HTTP APIs without a server process
- S3: react to uploads, deletions, metadata changes
- DynamoDB Streams: fire on every insert, update, or delete in a table
- SQS: pull messages off a queue automatically, with built-in retry
- SNS: fan-out from a single notification to multiple functions
- EventBridge: scheduled rules, cross-account events, partner integrations
Synchronous callers (API Gateway, a direct Invoke) wait for the response and see errors directly. Asynchronous ones (S3, SNS, EventBridge) hand the event over and let Lambda retry on failure, so make those handlers safe to run twice for the same event.
Costs
Two billing dimensions, per the Lambda pricing page (US East (N. Virginia) prices as listed in October 2026):
- Requests: the first 1 million per month are free, then $0.20 per million.
- Compute time: billed per millisecond, in GB-seconds (memory × duration). The first 400,000 GB-seconds per month are free; above that, x86 functions cost $0.0000166667 per GB-second in the first pricing tier.
Worked example from that page: 3 million requests a month at 120 ms and 1,536 MB comes to 540,000 GB-seconds, of which 140,000 are billable, for about $2.73 a month in total. A job that runs for a few seconds a day stays far inside the free allowance. Other services your function uses (S3, API Gateway, CloudWatch Logs, NAT gateways if it runs in a VPC) are billed separately.
Lambda gets expensive under sustained high-throughput load, where the function is busy most of the time. At that point, an EC2 instance or Fargate task can be cheaper. Where the crossover sits depends on memory, duration and traffic shape, so model your own numbers with the pricing calculator.
Local Development
Editing code in the AWS console is fine for a first function. After that you'll want a real workflow:
- SAM CLI:
sam local invokeruns your function inside a Docker container that mimics the Lambda environment. - LocalStack: runs emulated versions of S3, DynamoDB, SQS and other services on your machine, for integration tests where your function talks to other services.
- Plain testable code: keep the handler thin. Put the logic in regular Python modules that you test with pytest; the handler just unpacks the event, calls the logic and returns the response.
# lambda_function.py
import urllib.parse
from processor import process_file

def lambda_handler(event, context):
    record = event['Records'][0]
    bucket = record['s3']['bucket']['name']
    key = urllib.parse.unquote_plus(record['s3']['object']['key'])

    # process_file() is plain Python and can be unit tested with pytest
    result = process_file(bucket, key)

    return {'statusCode': 200, 'body': result}
Backend Example: Contact Form Handler
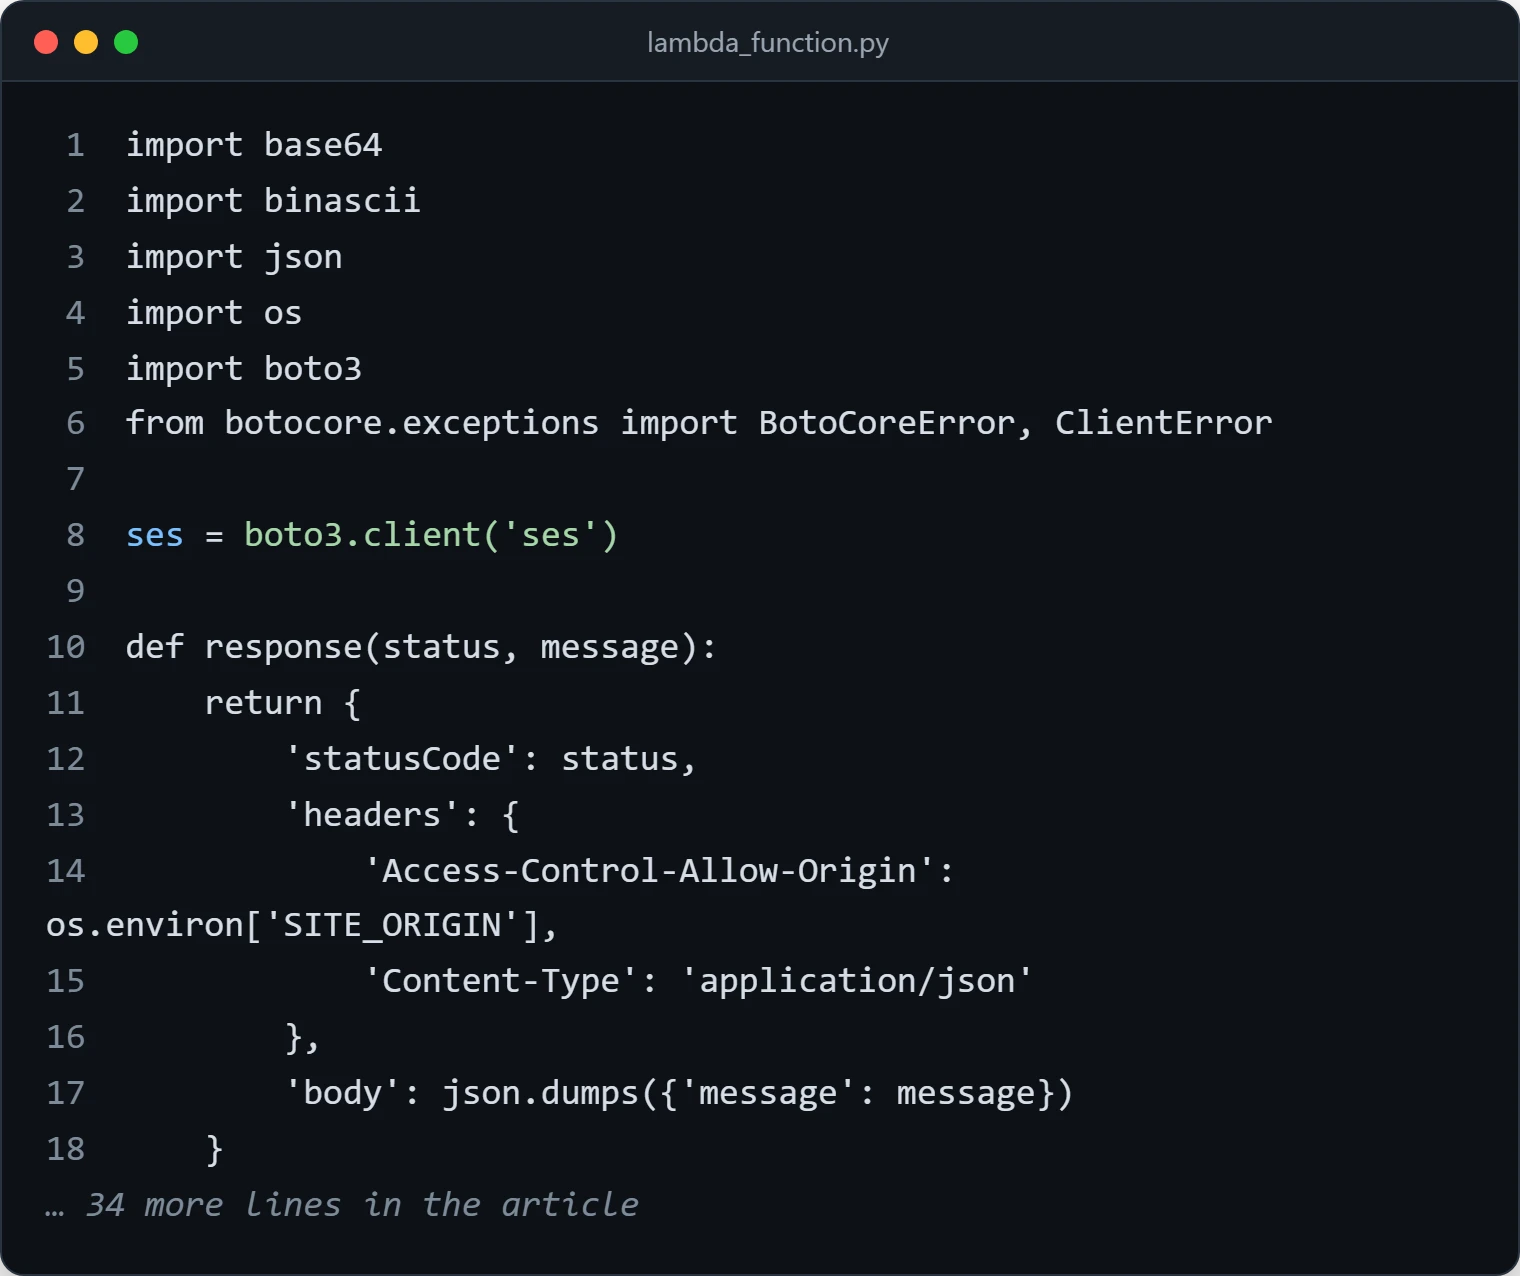
A common pattern for static sites: an HTML form posts to API Gateway, Lambda picks it up and sends an email through SES:
import base64
import binascii
import json
import os
import boto3
from botocore.exceptions import BotoCoreError, ClientError

ses = boto3.client('ses')

def response(status, message):
    return {
        'statusCode': status,
        'headers': {
            'Access-Control-Allow-Origin': os.environ['SITE_ORIGIN'],
            'Content-Type': 'application/json'
        },
        'body': json.dumps({'message': message})
    }

def lambda_handler(event, context):
    # API Gateway handles OPTIONS and accepts POST only.
    raw = event.get('body') or ''
    if not isinstance(raw, str) or len(raw) > 16000:
        return response(400, 'Invalid request body')
    try:
        if event.get('isBase64Encoded'):
            raw = base64.b64decode(raw, validate=True).decode('utf-8')
        body = json.loads(raw)
    except (ValueError, UnicodeError, binascii.Error):
        return response(400, 'Invalid JSON')
    if not isinstance(body, dict):
        return response(400, 'Expected a JSON object')
    limits = {'name': 100, 'email': 200, 'message': 5000}
    for field, limit in limits.items():
        value = body.get(field)
        if not isinstance(value, str) or not value.strip() or len(value) > limit:
            return response(400, 'Invalid form fields')
    name, email, message = (body[key].strip() for key in limits)
    if '\r' in name or '\n' in name or '\r' in email or '\n' in email or '@' not in email:
        return response(400, 'Invalid name or email')
    try:
        ses.send_email(
            Source=os.environ['FROM_EMAIL'],
            Destination={'ToAddresses': [os.environ['TO_EMAIL']]},
            Message={
                'Subject': {'Data': f'Contact form: {name}'},
                'Body': {'Text': {'Data': f'From: {name} ({email})\n\n{message}'}}
            }
        )
    except (BotoCoreError, ClientError):
        return response(502, 'Delivery failed; try again later')
    return response(200, 'Email sent successfully')
This is a backend handler sketch, not a complete deployed form. It omits the HTML client, API Gateway route and integration, and deployment configuration. A browser posting JSON also needs an OPTIONS preflight response: configure API Gateway CORS for the exact site origin, POST and the Content-Type header, and ensure error responses carry the appropriate CORS headers. Before it goes live:
- The execution role needs permission to call
ses:SendEmail, and the sender address or domain must be verified in SES. New SES accounts start in the sandbox, where recipients must be verified too. - The endpoint is public and unauthenticated, so anyone can call it. Add API Gateway throttling, validate and length-limit the fields, and consider a CAPTCHA, or it becomes a spam relay into your inbox.
- Set
Access-Control-Allow-Originto your site's real origin rather than*, and setSITE_ORIGIN,FROM_EMAILandTO_EMAILas environment variables. CORS controls browser access; it does not authenticate callers or stop server-to-server abuse.
Troubleshooting
- "Task timed out after 3.00 seconds": the default timeout. Check the
REPORTlines for normal duration and raise the timeout above it. If the function runs in a VPC and calls the internet, it needs a NAT gateway route (Lambda functions in a VPC don't get public IPs), or a VPC endpoint for AWS services such as S3. If it hangs on a network call, set explicit timeouts in your HTTP client so the error is yours, not Lambda's. - AccessDenied / "is not authorized to perform": the execution role is missing a permission. The error names the action and resource; add exactly that to the role's policy. For S3, remember object actions use
bucket/*ands3:ListBucketuses the bucket ARN. - No logs at all: either the function was never invoked (check the trigger, and for S3 the event type and prefix filter) or the role can't write logs. A role without the
logs:CreateLogGroup,logs:CreateLogStreamandlogs:PutLogEventspermissions from the basic execution policy produces no log group. Also check you're looking in the same Region as the function. - "Unable to import module 'lambda_function'": the handler setting doesn't match the file/function name, the file isn't at the root of the zip, or a dependency is missing or was built for the wrong platform.
- The S3 trigger fires over and over: the function writes into the prefix that triggers it. Disable the trigger, then separate input and output locations.
- Slow first request: a cold start. Check
Init Durationin the logs and see the cold-start options above. KeyError: 'Records': the event isn't an S3 notification. The console's default test event and scheduled events have noRecordskey; create a test event from the console's S3 Put template, or handle each event shape separately.- The bucket isn't offered when adding the S3 trigger: the bucket is in a different Region from the function. Create the function in the bucket's Region.
- "Unable to import module" for a compiled package such as NumPy: the wheel was built for your laptop's OS or CPU. Rebuild with the
--platformcommand above for the function's architecture.
Cleaning Up
Deleting a function doesn't delete its triggers' source configuration, its log group or its execution role. Remove them in this order:
- On the function page, Configuration → Triggers: select the S3 and EventBridge triggers and delete them. Then delete the EventBridge rule itself under EventBridge → Rules.
- Delete the function.
- Delete the log group
/aws/lambda/my-first-function. - In IAM, delete the execution role the console created (its name starts with
my-first-function-role-). - Empty and delete the test bucket if you made one just for this.
aws lambda delete-function --function-name my-first-function
aws logs delete-log-group --log-group-name /aws/lambda/my-first-function

# Verify: both should now return a ResourceNotFoundException
aws lambda get-function --function-name my-first-function
aws logs describe-log-streams --log-group-name /aws/lambda/my-first-function
Where to Go Next
- Write a bucket-scoped execution role policy and test it with the policy simulator: Secure Your AWS Account with IAM.
- Put the contact form handler behind a static site: Host a Static Website on AWS.
- If a function has to run inside a VPC and still reach the internet, it needs private subnets with a NAT gateway route: Build a 3-Tier VPC Architecture covers that layout and its cost.
- For work that runs longer than 15 minutes, holds connections open, or is busy around the clock, an always-on instance is usually the better fit: AWS EC2 Deployment Guide.