What You Need Before Starting
- A running Ubuntu Server instance you can reach with
sshas theubuntuuser. - Security group inbound rules for SSH (22) from your own IP, and HTTP (80) and HTTPS (443) from anywhere. The launch guide sets these up.
- Your application in a Git repository, with a lockfile (
package-lock.jsonor a pinnedrequirements.txt), listening on a port you can set with aPORTenvironment variable. - For HTTPS: a domain name whose DNS records you can edit.
- An AWS Budgets cost alert. EC2 doesn't warn you about an instance you forgot; a low budget threshold turns a forgotten test box into an email instead of a line on the monthly bill. The IAM guide walks through creating one.
Versions this guide targets: Ubuntu Server 24.04 LTS (the commands use apt and the default ubuntu user; 22.04 LTS works the same way except that it ships Python 3.10) and Node.js 24. On the Node.js release schedule, 24.x moved to Maintenance LTS on October 20, 2026 and is supported until April 30, 2028, and 26.x becomes Active LTS on October 28, 2026. Node 24 remains a safe production choice; move to 26 once your dependencies support it. Ubuntu 26.04 LTS is also available on EC2, but NodeSource's published support table lists Ubuntu releases only up to 24.04, so check it before using the NodeSource step there. The Amazon EC2 User Guide is the reference for anything EC2-specific.
SSH In and Prepare the Server
Connect with the key pair you chose at launch:
ssh -i ~/.ssh/my-aws-key.pem ubuntu@YOUR-PUBLIC-IPTo shorten that to ssh myserver, add a block to ~/.ssh/config on your own machine:
Host myserver
    HostName YOUR-PUBLIC-IP
    User ubuntu
    IdentityFile ~/.ssh/my-aws-key.pem
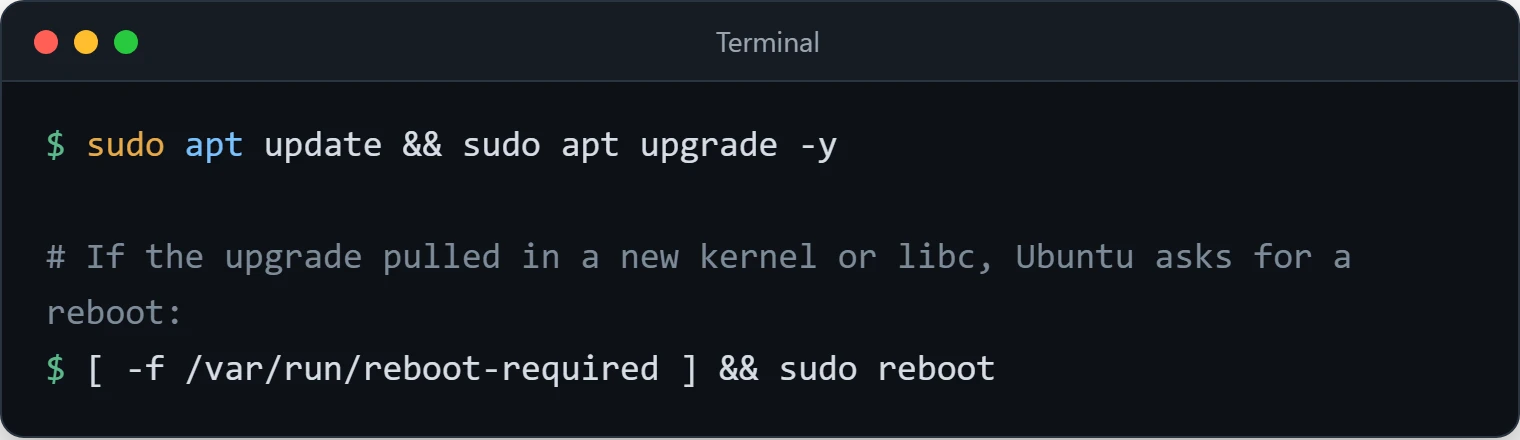
Update the package lists and installed packages first. A stale package list is a common reason for apt install failing with "Unable to locate package" or 404 errors on a fresh instance.
sudo apt update && sudo apt upgrade -y

# If the upgrade pulled in a new kernel or libc, Ubuntu asks for a reboot:
[ -f /var/run/reboot-required ] && sudo reboot
After a reboot, wait a minute and SSH back in. Without an Elastic IP the public address stays the same across a reboot; it only changes on a stop and start.
Install Runtime Dependencies
Pick the block for your stack.
Ubuntu's own nodejs package usually lags behind the upstream LTS line, so this uses NodeSource's repository for the 24.x line. Download the setup script first so you can read it before running it as root:
# Add the NodeSource repository for Node.js 24.x
curl -fsSL https://deb.nodesource.com/setup_24.x -o nodesource_setup.sh
less nodesource_setup.sh          # read what it does
sudo -E bash nodesource_setup.sh
sudo apt install -y nodejs

# Verify: the first line should start with v24.
node --version
npm --version
To use 26.x once it reaches LTS, change the number in the script URL to setup_26.x; the rest of the guide is the same. The script and its options are documented in the NodeSource distributions repository.
Ubuntu 24.04 ships Python 3.12. Since 23.04, Ubuntu marks the system Python as externally managed (PEP 668), so pip install outside a virtual environment fails with error: externally-managed-environment. Use a venv:
sudo apt install -y python3 python3-venv
python3 --version
You create the venv inside the app directory after cloning the code in the next section, because git clone refuses to clone into a directory that already has files in it.
If you're deploying with Docker, see the Docker installation guide and skip straight to the reverse proxy section. Docker's restart policies take the place of PM2 or systemd, so the process-manager section doesn't apply.
Get Your Code Onto the Server
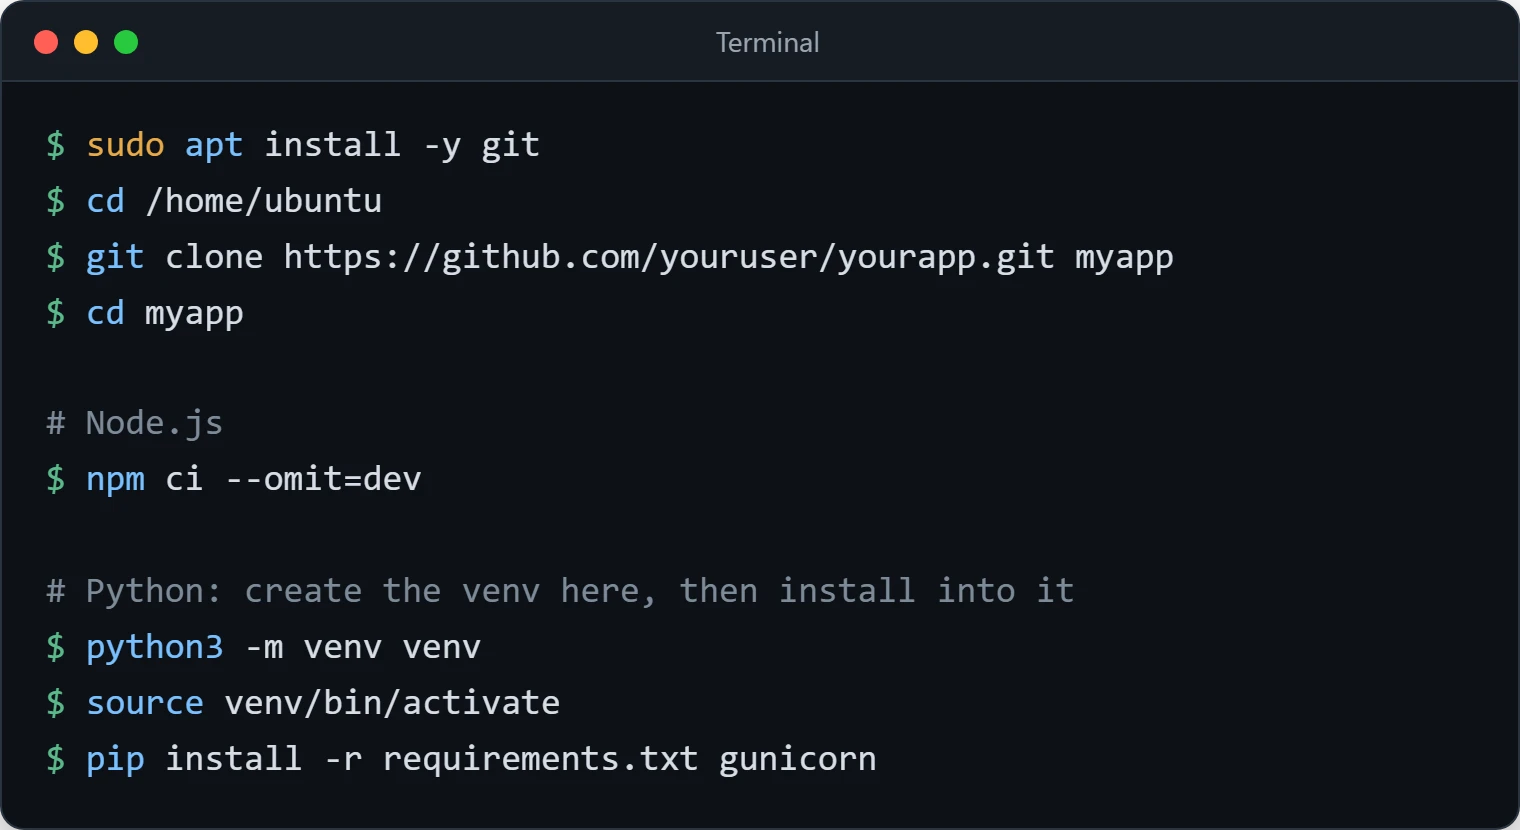
Three ways to do this. Git clone is the one to use for anything beyond a throwaway test, because every later deploy is a git pull. The rest of the guide assumes the code ends up in /home/ubuntu/myapp.
/home/ubuntu/myapp.sudo apt install -y git
cd /home/ubuntu
git clone https://github.com/youruser/yourapp.git myapp
cd myapp
# Node.js
npm ci --omit=dev
# Python: create the venv here, then install into it
python3 -m venv venv
source venv/bin/activate
pip install -r requirements.txt gunicornnpm ci installs exactly what package-lock.json lists and fails if the lockfile and package.json disagree, which is what you want on a server. --omit=dev skips development dependencies (see the npm ci docs). If the project has no lockfile, use npm install --omit=dev instead. For Python, gunicorn is the WSGI server the systemd unit below runs; drop it if your requirements file already includes it or you use a different server.
For private repos, either set up a deploy key (SSH key added to the repo settings) or use a fine-grained personal access token. Deploy keys are better because they're scoped to one repo.
Before adding a process manager, start the app by hand once to check that it runs: PORT=3000 node server.js (or venv/bin/gunicorn -b 127.0.0.1:8000 app:app), then from a second SSH session run curl -I http://127.0.0.1:3000 (port 8000 for gunicorn). Any HTTP status line means the app is answering. Stop it with Ctrl+C.
Fine for quick one-offs. scp copies every file on every run, which gets slow for projects with many small files such as a node_modules folder. rsync compares source and destination and only transfers what changed, so repeat deploys move far less data. Better still, don't copy node_modules at all; install dependencies on the server.
# From your local machine (scp — full copy every time)
scp -i ~/.ssh/my-aws-key.pem -r ./myapp ubuntu@YOUR-PUBLIC-IP:/home/ubuntu/

# rsync — only transfers changed files (use this one)
rsync -avz -e "ssh -i ~/.ssh/my-aws-key.pem" ./myapp/ ubuntu@YOUR-PUBLIC-IP:/home/ubuntu/myapp/This is the CI/CD path: build your artifact in a pipeline, push it to S3, pull it on the instance. Install AWS CLI version 2 first, using the installer or the snap package described in the AWS CLI install guide. AWS doesn't maintain the distribution's awscli apt package, so it can be old or missing on newer Ubuntu releases.
# Pull your artifact
aws s3 cp s3://your-bucket/builds/myapp-latest.tar.gz /home/ubuntu/
mkdir -p /home/ubuntu/myapp
tar -xzf /home/ubuntu/myapp-latest.tar.gz -C /home/ubuntu/myapp
This needs an IAM role on the instance. Attach an instance profile with read access to that one bucket (the IAM guide shows how to scope a policy). Don't paste long-lived AWS access keys into a file on the server: the role gives the CLI temporary credentials automatically, and keys in files tend to end up in backups or commits.
Keep It Running with a Process Manager
If you start your app with node server.js directly, it dies the moment you close your SSH session. You need something to keep it alive and restart it after crashes.
Two common choices. PM2 is a Node.js process manager with a cluster mode and a built-in log viewer, but it is one more piece of software to install, update and keep running. systemd is already on every Ubuntu instance and can restart your process without extra software, and its logs go to the journal like everything else on the system. PM2 is quicker to start with; systemd has fewer moving parts. Pick whichever you'll actually maintain. Running Your Scripts as Real Services with Systemd goes deeper into unit files, restart policies and logs.
# Install PM2 globally
sudo npm install -g pm2

# Start your application
cd /home/ubuntu/myapp
PORT=3000 NODE_ENV=production pm2 start server.js --name myapp

# Set PM2 to start on boot. It prints a sudo command: copy and run it.
pm2 startup systemd

# Save the current process list; this is what PM2 restores at boot
pm2 save

# Verify: status "online", and the app answers locally
pm2 list
curl -I http://127.0.0.1:3000
Useful PM2 commands for later:
pm2 list              # See running processes
pm2 logs myapp        # Tail the logs
pm2 restart myapp     # Restart after a code update
pm2 monit # Real-time resource monitorAlready on the server. No install. Create a service file:
sudo nano /etc/systemd/system/myapp.servicePaste this, adjusting the paths and command:
[Unit]
Description=My Application
After=network.target

[Service]
Type=simple
User=ubuntu
WorkingDirectory=/home/ubuntu/myapp
ExecStart=/usr/bin/node server.js
Restart=on-failure
RestartSec=5
Environment=NODE_ENV=production
Environment=PORT=3000

[Install]
WantedBy=multi-user.target
Then enable and start it:
sudo systemctl daemon-reload
sudo systemctl enable --now myapp

# Verify: "active (running)", and the app answers locally
sudo systemctl status myapp --no-pager
curl -I http://127.0.0.1:3000
For a Python app, change ExecStart to something like /home/ubuntu/myapp/venv/bin/gunicorn -w 2 -b 127.0.0.1:8000 app:app and use port 8000 in the Nginx config below. Gunicorn's docs suggest starting from (2 × CPU cores) + 1 workers; on a 1 GiB burstable instance, fewer workers leave more memory for the app. To confirm the unit survives a reboot, run sudo reboot, reconnect, and check systemctl is-active myapp.
Put Nginx in Front
Your app listens on 3000 or 8000. Nobody should have to type :3000 in a URL. Nginx sits in front and proxies traffic from port 80 to your app, which also lets you keep the app itself bound to 127.0.0.1 where the internet can't reach it directly. The Nginx Web Server Setup guide covers server blocks, TLS and security headers in more detail.
sudo apt install -y nginxCreate a config at /etc/nginx/sites-available/myapp:
sudo nano /etc/nginx/sites-available/myappWatch for a trailing slash (or any path) on the proxy_pass URL. Without a path, as in proxy_pass http://127.0.0.1:3000;, Nginx forwards the request URI unchanged. With a path, as in proxy_pass http://127.0.0.1:3000/;, the part of the URI that matched the location is replaced by that path. For location / the two behave the same, but under something like location /api/ the slash version turns /api/users into /users at the app. If routes return 404 through Nginx but work when you curl the app directly, check this first. The rules are in the proxy_pass documentation.
# Send "Connection: upgrade" only when the client asked for a WebSocket upgrade
map $http_upgrade $connection_upgrade {
    default upgrade;
    ''      close;
}

server {
    listen 80;
    server_name yourdomain.com www.yourdomain.com;

    location / {
        proxy_pass http://127.0.0.1:3000;
        proxy_http_version 1.1;
        proxy_set_header Upgrade $http_upgrade;
        proxy_set_header Connection $connection_upgrade;
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;
    }
}
The map block is the pattern from Nginx's WebSocket proxying page. Files in sites-enabled are included inside the http context, so map is valid at the top of this file. Define it once per server; a second site with the same map makes nginx -t fail with a duplicate variable error.
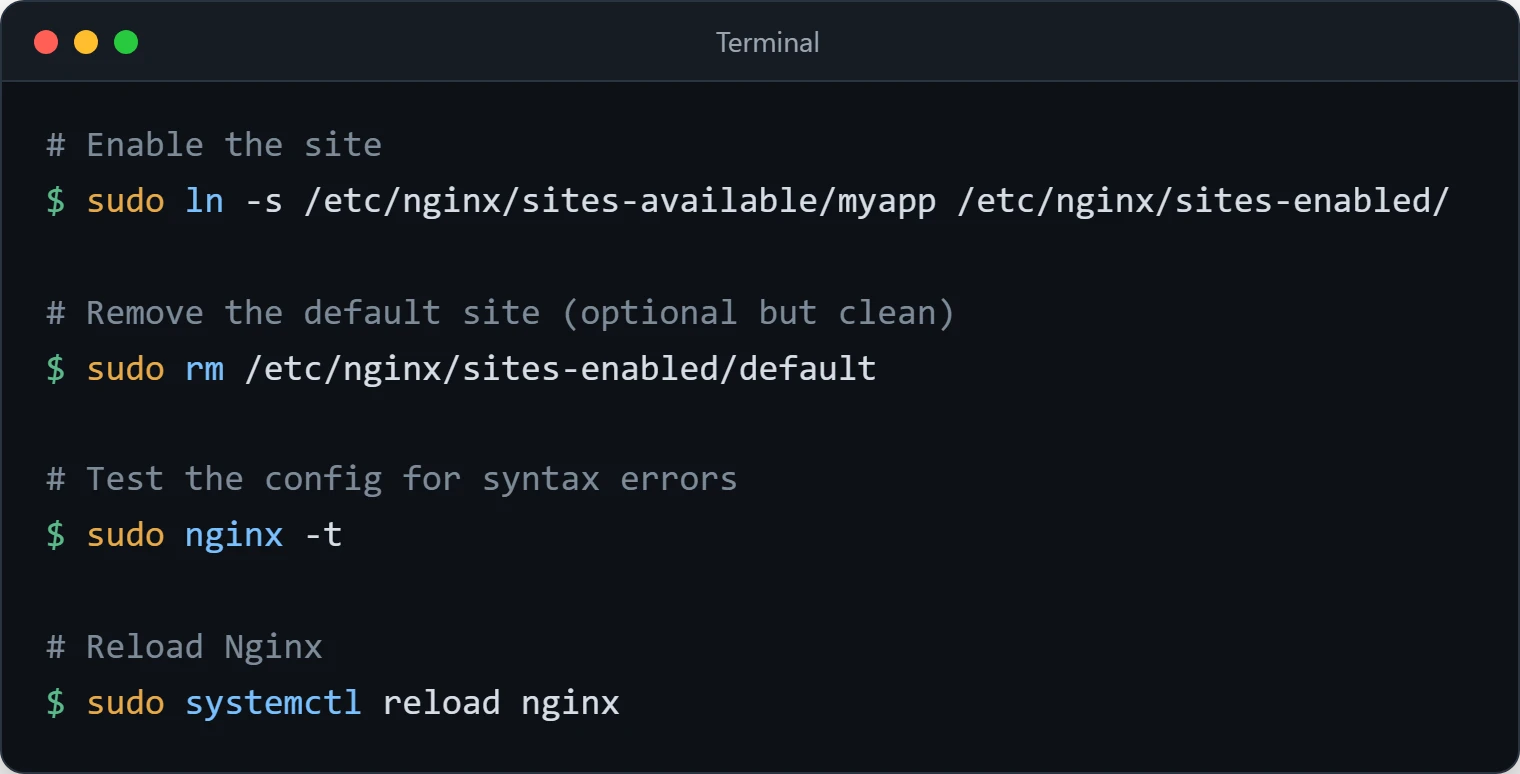
Enable it and reload Nginx:
# Enable the site
sudo ln -s /etc/nginx/sites-available/myapp /etc/nginx/sites-enabled/

# Remove the default site (optional but clean)
sudo rm /etc/nginx/sites-enabled/default

# Test the config for syntax errors
sudo nginx -t

# Reload Nginx
sudo systemctl reload nginx
Check it from the instance first, then from outside:
# On the instance: Nginx should return your app's response, not the Nginx welcome page
curl -I -H "Host: yourdomain.com" http://127.0.0.1

# From your own machine
curl -I http://YOUR-PUBLIC-IP
If the first works and the second times out, the problem is the security group, not Nginx (see the troubleshooting section).
HTTPS with Let's Encrypt
Point your domain's DNS at the instance (an Elastic IP keeps the address stable across stop/start) and open port 443 in the security group. Certbot's official instructions install it as a snap; the Ubuntu packages certbot and python3-certbot-nginx also work. With the Nginx plugin, Certbot gets the certificate, edits the server block to use it and sets up automatic renewal.
# Official method (snap)
sudo snap install --classic certbot
sudo ln -s /snap/bin/certbot /usr/local/bin/certbot

# Get a certificate and let Certbot edit the Nginx config
sudo certbot --nginx -d yourdomain.com -d www.yourdomain.com

# Confirm renewal will work, and that the renewal timer exists
sudo certbot renew --dry-run
systemctl list-timers 'snap.certbot*'

# From your own machine: expect an HTTP/1.1 200 (or your app's status) over HTTPS
curl -I https://yourdomain.com
Certbot's HTTP challenge needs port 80 reachable from the internet and DNS already pointing at this instance. If DNS still points somewhere else, wait for the old record's TTL to expire before running it; Let's Encrypt rate-limits repeated failed validations.
Logs and Monitoring
Your app is running. Now you need to know when it stops. For PM2: pm2 logs myapp --lines 100. For systemd: sudo journalctl -u myapp -f. The -f flag tails the log in real time — leave that open in a second terminal while you're testing.
Nginx keeps its own logs:
sudo tail -f /var/log/nginx/access.log
sudo tail -f /var/log/nginx/error.log
When a request fails through Nginx, check the error log first. For proxy problems it names the upstream address and the reason, such as connect() failed (111: Connection refused).
htop (sudo apt install -y htop) shows memory and CPU per process more readably than top. Run df -h now and then: a full root volume makes writes fail, and logs written to disk without rotation are the usual cause. sudo journalctl --disk-usage shows how much space the journal itself takes.
If this is running in production, set up a CloudWatch alarm on the instance's CPUUtilization metric, for example "alert when the average is above 80% for 5 minutes", plus the instance's status-check alarms. That catches a runaway process or a failed host before your users report it. Alarm pricing is on the CloudWatch pricing page.
Deploying Updates
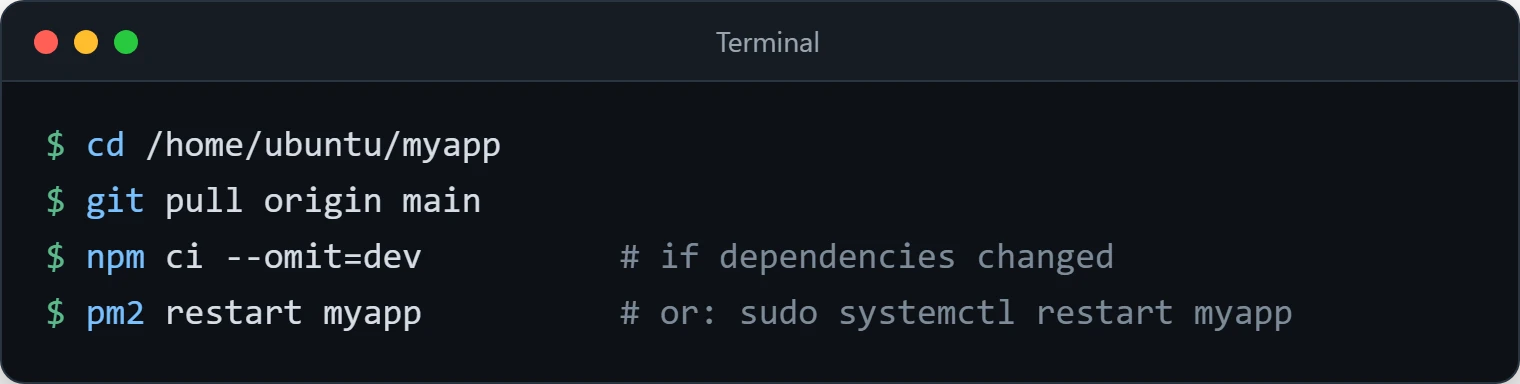
After the initial setup, updating is a pull, a dependency install and a restart. Git-based, Node.js:
cd /home/ubuntu/myapp
git pull origin main
npm ci --omit=dev          # if dependencies changed
pm2 restart myapp          # or: sudo systemctl restart myapp
Git-based, Python:
cd /home/ubuntu/myapp
git pull origin main
venv/bin/pip install -r requirements.txt
sudo systemctl restart myapp
Then confirm the new version is the one answering: curl -I https://yourdomain.com, and sudo journalctl -u myapp -n 20 --no-pager (or pm2 logs myapp --lines 20) for startup errors.
Rsync-based (run from your local machine):
rsync -avz -e "ssh -i ~/.ssh/my-aws-key.pem" ./myapp/ ubuntu@YOUR-PUBLIC-IP:/home/ubuntu/myapp/
ssh myserver "pm2 restart myapp"
A restart leaves a short gap while the process stops and starts again, and Nginx answers with 502 during that gap. For a single-server setup that is usually acceptable. For apps running in PM2's cluster mode, pm2 reload does a zero-downtime reload instead (see PM2's cluster mode docs); on a single small instance it's rarely worth the added complexity.
Things That Will Go Wrong
App works on localhost:3000 but not from outside
Work from the outside in. The error your browser or curl shows tells you which layer to look at:
- Connection timed out (the request hangs, then fails): packets are being dropped before they reach a listening process. That points at the security group, a network ACL, the subnet's route table, or a host firewall. In the EC2 console, open the instance's Security tab and check that the security group has an inbound rule for TCP 80 (and 443) from the source you're testing from. Security groups are stateful, so you don't need a matching outbound rule for the reply. If you enabled UFW, run
sudo ufw statusand allow the port there too. - Connection refused (fails immediately): the packet reached the instance, but nothing is listening on that port. Check Nginx with
sudo systemctl status nginxand list listening sockets withsudo ss -tlnp; you should see Nginx on:80. - Nginx answers but shows its default page or a 404: your server block isn't the one handling the request. Check that the symlink exists in
sites-enabled, thatserver_namematches the host you typed, and runsudo nginx -t.
Also confirm you're using the instance's current public IP: without an Elastic IP, the public IPv4 address changes when you stop and start the instance. The EC2 guide on troubleshooting connections covers the SSH side of the same problem.
502 Bad Gateway
Nginx is working, but the app behind it isn't responding. Run pm2 list or sudo systemctl status myapp to see if the app is even alive, then sudo ss -tlnp | grep 3000 to confirm it's listening on the right port.
# Quick check: is anything listening on port 3000?
sudo ss -tlnp | grep 3000
If the app is listening but Nginx still returns 502, compare the address in ss with the one in proxy_pass. A common mismatch: proxy_pass http://localhost:3000 while the app listens only on IPv4. localhost can resolve to both 127.0.0.1 and the IPv6 address ::1, and a connection to ::1 is refused if the app isn't listening there. Use the explicit address 127.0.0.1 in proxy_pass. The Nginx error log (/var/log/nginx/error.log) names the upstream address it failed to reach. Avoid "fixing" it by binding the app to 0.0.0.0, which exposes it on every interface.
App crashes on startup
Read the logs: pm2 logs myapp --err --lines 50 or sudo journalctl -u myapp --no-pager -n 50. Common causes are a missing environment variable, or dependencies that weren't reinstalled after pulling code that added a new one.
If systemctl status myapp shows status=203/EXEC, systemd couldn't execute the ExecStart binary at all: the path is wrong or the file isn't executable. Check it with command -v node (NodeSource installs to /usr/bin/node) or ls -l /home/ubuntu/myapp/venv/bin/gunicorn. status=200/CHDIR means the WorkingDirectory doesn't exist. The codes are listed under "Process Exit Codes" in the systemd.exec manual.
The app is gone after a reboot (PM2)
pm2 startup only prints a command; nothing is installed until you run that command with sudo. After that, pm2 save has to run while the app is online, because PM2 restores the saved list at boot. Run systemctl status pm2-ubuntu to see whether the boot unit exists. The PM2 startup docs also say to run pm2 unstartup and then pm2 startup again after upgrading Node.js, since the unit stores the path to the Node binary.
Certbot fails to get a certificate
The error usually names the problem. "Timeout during connect (likely firewall problem)" means Let's Encrypt couldn't reach port 80 on your domain: check the security group and that DNS points at this instance's current public IP. "DNS problem: NXDOMAIN" means the record doesn't exist yet or hasn't propagated; dig +short yourdomain.com should print your instance's IP before you retry. The challenge types page explains what the HTTP-01 check needs.
When You're Done
The most expensive EC2 resource is the one you forgot about. After you finish a project, a test, or a demo, check what's still running. These three commands will tell you:
# List all running instances in your current region
aws ec2 describe-instances \
  --filters "Name=instance-state-name,Values=running" \
  --query "Reservations[].Instances[].[InstanceId, InstanceType, LaunchTime, Tags[?Key=='Name'].Value | [0]]" \
  --output table
# Check every enabled region (a forgotten test instance is often in a region you rarely look at)
for region in $(aws ec2 describe-regions --query "Regions[].RegionName" --output text); do
echo "--- $region ---"
aws ec2 describe-instances --region "$region" \
--filters "Name=instance-state-name,Values=running" \
--query "Reservations[].Instances[].[InstanceId, InstanceType]" \
--output text
done# Terminate a specific instance when you're sure you're done with it
aws ec2 terminate-instances --instance-ids i-0abc123def456789Run the first command after every deployment session and the second one monthly. Use the third when you find something that shouldn't be there; it deletes the instance and, by default, its root volume, so snapshot anything you want to keep first. Terminating an instance doesn't release an Elastic IP, and EBS volumes created with "Delete on termination" turned off survive too. Both keep billing:
# Elastic IPs with no AssociationId are idle but still charged per hour
aws ec2 describe-addresses \
  --query "Addresses[].[PublicIp, AllocationId, AssociationId]" --output table
aws ec2 release-address --allocation-id eipalloc-0abc123def456789

# Unattached EBS volumes ("available" status)
aws ec2 describe-volumes --filters Name=status,Values=available \
  --query "Volumes[].[VolumeId, Size, CreateTime]" --output table
These commands need the AWS CLI configured on your own machine with permission to describe and terminate EC2 resources.
Where to Go Next
- Harden remote access with key-only SSH and Fail2Ban: Locking Down SSH.
- Add restart limits, environment files and timers to the unit: Running Your Scripts as Real Services with Systemd.
- Move the app into private subnets behind a load balancer once one instance isn't enough: Build a 3-Tier VPC Architecture.
- Hand short, event-driven jobs to Lambda instead of running them on the instance.