What you need
- A Linux host with Docker Engine and the Compose plugin. The Docker Installation Guide covers Ubuntu, Debian, Fedora, RHEL and CentOS Stream.
- Local disk for the metrics database. Prometheus's storage docs estimate 1–2 bytes per sample, and say NFS (including AWS EFS) is not supported for its local storage. The storage section shows how to estimate and cap the size.
- For notifications: a Telegram account to create a bot, or an SMTP account that allows authenticated sending.
The files pin these images, which were the current releases on each project's release page on October 9, 2026:
| Component | Image | Port |
|---|---|---|
| Prometheus | prom/prometheus:v3.15.0 | 9090, bound to 127.0.0.1 |
| Alertmanager | prom/alertmanager:v0.34.1 | 9093, bound to 127.0.0.1 |
| Grafana | grafana/grafana:13.2.3 | 3000, bound to 127.0.0.1 |
| node_exporter | prom/node-exporter:v1.12.1 | 9100 on the host network |
| cAdvisor | ghcr.io/google/cadvisor:0.60.6 | 8080, Compose network only |
Prometheus, Alertmanager, node_exporter and cAdvisor have no login of their own. Grafana, Prometheus and Alertmanager are bound to loopback and reached through an SSH tunnel, shown later. cAdvisor is only on the Compose network. node_exporter uses the host network on port 9100: restrict that port with your host or cloud firewall before starting the stack. Do not assume it is private merely because Compose has no ports entry for it.
Create the project directory
Everything lives in one directory, so it can go into Git (minus the secrets) and be rebuilt elsewhere:
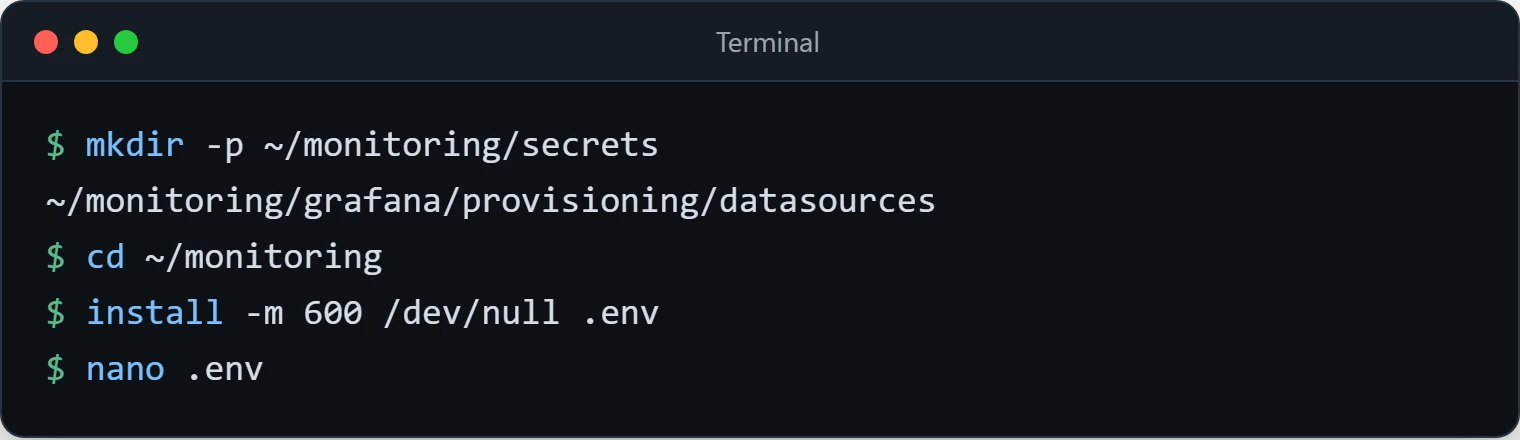
.env that only you can read.monitoring/
├── compose.yaml
├── .env # Grafana admin password (not in Git)
├── prometheus.yml
├── alert_rules.yml
├── alertmanager.yml
├── secrets/telegram_token # or secrets/smtp_password (not in Git)
└── grafana/provisioning/datasources/prometheus.ymlmkdir -p ~/monitoring/secrets ~/monitoring/grafana/provisioning/datasources
cd ~/monitoring
install -m 600 /dev/null .env
nano .envPut one line in .env, with a long random password of your own:
GRAFANA_ADMIN_PASSWORD=use-a-long-random-password-herecompose.yaml
name: monitoring

services:
  prometheus:
    image: prom/prometheus:v3.15.0
    command:
      - --config.file=/etc/prometheus/prometheus.yml
      - --storage.tsdb.path=/prometheus
      - --storage.tsdb.retention.time=30d
      - --storage.tsdb.retention.size=10GB
    ports:
      - "127.0.0.1:9090:9090"
    volumes:
      - ./prometheus.yml:/etc/prometheus/prometheus.yml:ro
      - ./alert_rules.yml:/etc/prometheus/alert_rules.yml:ro
      - prometheus_data:/prometheus
    extra_hosts:
      - "host.docker.internal:host-gateway"
    restart: unless-stopped

  alertmanager:
    image: prom/alertmanager:v0.34.1
    ports:
      - "127.0.0.1:9093:9093"
    volumes:
      - ./alertmanager.yml:/etc/alertmanager/alertmanager.yml:ro
      - ./secrets:/etc/alertmanager/secrets:ro
      - alertmanager_data:/alertmanager
    restart: unless-stopped

  grafana:
    image: grafana/grafana:13.2.3
    ports:
      - "127.0.0.1:3000:3000"
    environment:
      GF_SECURITY_ADMIN_PASSWORD: ${GRAFANA_ADMIN_PASSWORD:?set GRAFANA_ADMIN_PASSWORD in .env}
    volumes:
      - ./grafana/provisioning/datasources:/etc/grafana/provisioning/datasources:ro
      - grafana_data:/var/lib/grafana
    restart: unless-stopped

  node_exporter:
    image: prom/node-exporter:v1.12.1
    command:
      - --path.rootfs=/host
    network_mode: host
    pid: host
    volumes:
      - /:/host:ro,rslave
    restart: unless-stopped

  cadvisor:
    image: ghcr.io/google/cadvisor:0.60.6
    privileged: true
    devices:
      - /dev/kmsg
    volumes:
      - /:/rootfs:ro
      - /var/run:/var/run:ro
      - /sys:/sys:ro
      - /var/lib/docker/:/var/lib/docker:ro
      - /dev/disk/:/dev/disk:ro
    restart: unless-stopped

volumes:
  prometheus_data:
  alertmanager_data:
  grafana_data:
A few lines need explaining:
name: monitoringfixes the Compose project name, so the volumes are always calledmonitoring_prometheus_dataand so on, whatever the directory is called. The backup commands below rely on that.- node_exporter uses the host's network and PID namespaces and a read-only view of
/with--path.rootfs=/host, as the node_exporter README requires for container installs. Without that it would report the container instead of the host. Prometheus reaches it throughhost.docker.internal, whichextra_hostsmaps to the host's address on the Docker bridge. - cAdvisor uses the mounts and
privilegedflag from the cAdvisor README. Privileged means the container has full access to the host; that's the price of reading every container's cgroups. Leave the service out if you only want host metrics. It isn't published on any host port, because Prometheus scrapes it over the Compose network. - Grafana's password comes from
.env, and the:?syntax makes Compose refuse to start if it's missing. Grafana only applies it when it creates its database on the first start; changing it later has no effect (see troubleshooting). - Port 3000 is bound to loopback. Keep that binding when you use the SSH tunnel, because Docker-published ports can bypass host firewall rules. Put Grafana behind HTTPS if you need browser access without a tunnel; the Nginx Web Server Setup covers reverse proxying.
prometheus.yml
global:
  scrape_interval: 15s
  evaluation_interval: 15s

rule_files:
  - /etc/prometheus/alert_rules.yml

alerting:
  alertmanagers:
    - static_configs:
        - targets: ['alertmanager:9093']

scrape_configs:
  - job_name: 'prometheus'
    static_configs:
      - targets: ['localhost:9090']

  - job_name: 'node'
    static_configs:
      - targets: ['host.docker.internal:9100']

  - job_name: 'cadvisor'
    static_configs:
      - targets: ['cadvisor:8080']
Containers on the same Compose network find each other by service name, so alertmanager:9093 and cadvisor:8080 need no IP addresses. Remove the cadvisor job if you left that service out. Every key is described in the configuration reference.
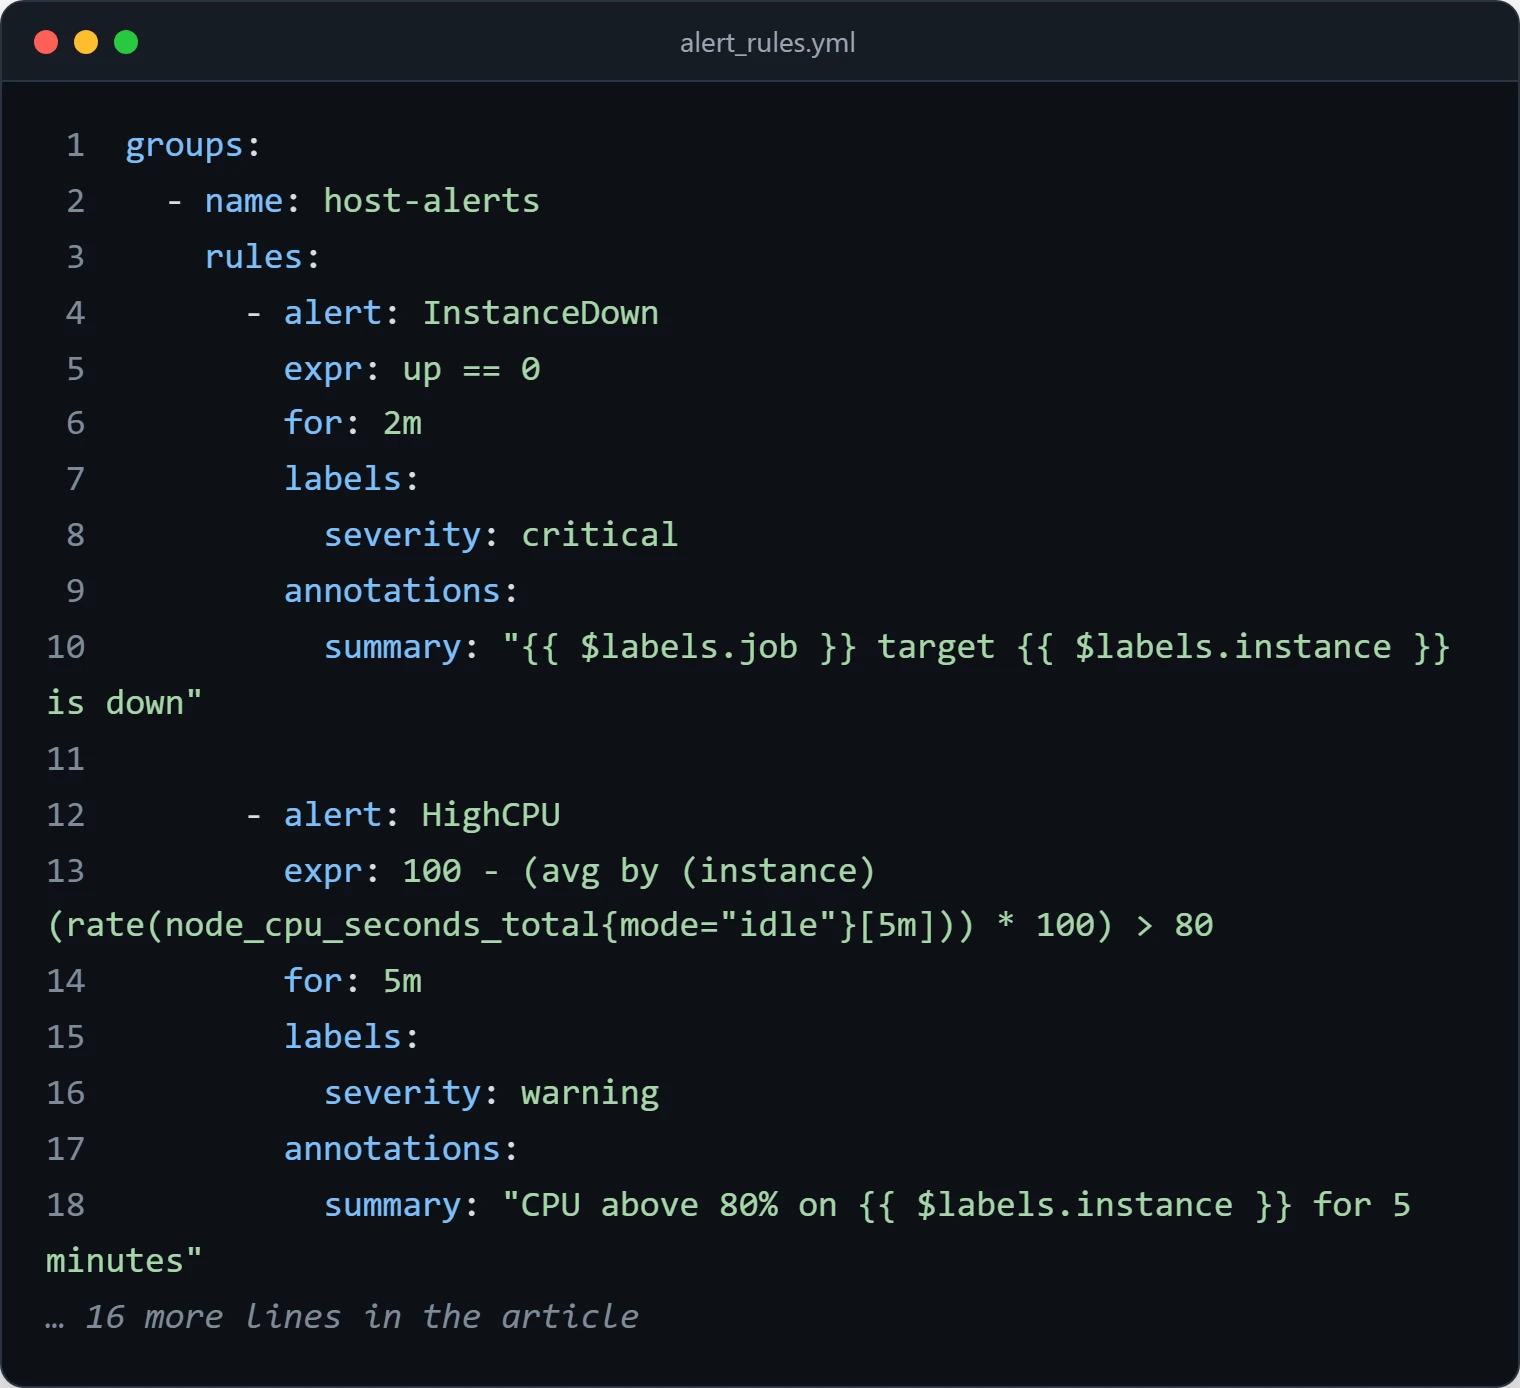
alert_rules.yml
groups:
  - name: host-alerts
    rules:
      - alert: InstanceDown
        expr: up == 0
        for: 2m
        labels:
          severity: critical
        annotations:
          summary: "{{ $labels.job }} target {{ $labels.instance }} is down"

      - alert: HighCPU
        expr: 100 - (avg by (instance) (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100) > 80
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: "CPU above 80% on {{ $labels.instance }} for 5 minutes"

      - alert: LowMemory
        expr: (1 - (node_memory_MemAvailable_bytes / node_memory_MemTotal_bytes)) * 100 > 90
        for: 10m
        labels:
          severity: warning
        annotations:
          summary: "Less than 10% memory available on {{ $labels.instance }}"

      - alert: DiskSpaceLow
        expr: (1 - (node_filesystem_avail_bytes{fstype!~"tmpfs|overlay"} / node_filesystem_size_bytes{fstype!~"tmpfs|overlay"})) * 100 > 85
        for: 10m
        labels:
          severity: critical
        annotations:
          summary: "{{ $labels.mountpoint }} on {{ $labels.instance }} is over 85% full"
up == 0fires when Prometheus can't scrape a target, which covers a stopped exporter or crashed container while Prometheus is still running. It can detect a powered-off remote target, but this single-host setup cannot notify you when its own host loses power: Prometheus and Alertmanager stop too. Use an independent external uptime probe or a heartbeat receiver on another host; alert when its expected heartbeat is missing, and test that path by stopping this monitoring host during a maintenance window.for:is how long the condition must hold before the alert fires, so a short spike doesn't wake you up.node_memory_MemAvailable_bytesis the kernel's estimate of memory available to new programs, including cache it can drop, so the memory rule doesn't fire just because Linux uses spare RAM as cache.- The disk rule skips
tmpfsandoverlay, which otherwise produce noise from RAM disks and container layers.
alertmanager.yml
Alertmanager groups alerts and decides where they go. Pick one of the two receivers.
Telegram
route:
  receiver: 'telegram'
  group_by: ['alertname', 'instance']
  group_wait: 30s
  group_interval: 5m
  repeat_interval: 4h

receivers:
  - name: 'telegram'
    telegram_configs:
      - bot_token_file: /etc/alertmanager/secrets/telegram_token
chat_id: 123456789- In Telegram, talk to @BotFather, create a bot and copy the token it gives you.
- Send any message to your new bot, then open
https://api.telegram.org/bot<token>/getUpdatesin a browser. Theidinside thechatobject is the number forchat_id; replace123456789with it. - Save the token in a file the container can read. The Alertmanager image runs as the
nobodyuser (UID 65534):
install -m 600 /dev/null secrets/telegram_token
nano secrets/telegram_token            # paste the token, nothing else
sudo chown 65534 secrets/telegram_token
Using bot_token_file instead of bot_token keeps the token out of alertmanager.yml, so that file can go into Git. The timing values shown are Alertmanager's defaults, written out so you can tune them: wait 30 seconds to batch related alerts, send updates to a group at most every 5 minutes, and repeat an unresolved alert every 4 hours. Telegram receivers also send a message when an alert resolves, because send_resolved defaults to true there.
route:
  receiver: 'email'
  group_by: ['alertname', 'instance']

receivers:
  - name: 'email'
    email_configs:
      - to: 'alerts@example.com'
        from: 'prometheus@example.com'
        smarthost: 'smtp.example.com:587'
        auth_username: 'alerts@example.com'
        auth_password_file: /etc/alertmanager/secrets/smtp_password
        send_resolved: true
Replace the addresses and server with your provider's. Create secrets/smtp_password the same way as the Telegram token. For email, send_resolved defaults to false in the Alertmanager configuration reference, so it's switched on explicitly. Port 587 with STARTTLS is the usual submission setup; TLS is required by default.
Give Grafana its data source
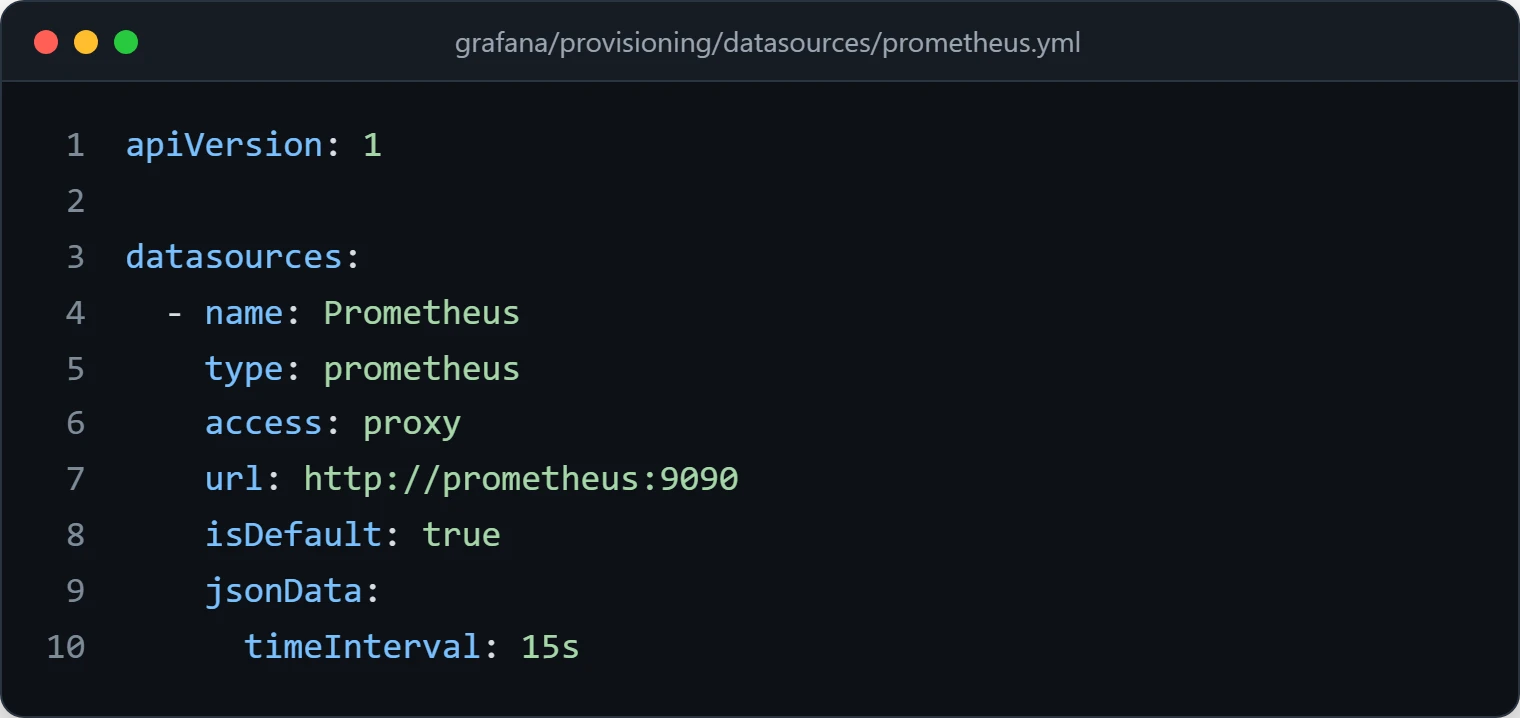
Rather than clicking through the UI after every rebuild, describe the data source in a provisioning file. Grafana reads it at startup:
apiVersion: 1

datasources:
  - name: Prometheus
    type: prometheus
    access: proxy
    url: http://prometheus:9090
    isDefault: true
    jsonData:
      timeInterval: 15s
The URL uses the service name: inside the Grafana container, localhost is Grafana itself, as the Prometheus data source docs point out. timeInterval matches the scrape interval. Grafana doesn't let you edit a provisioned data source in the UI; change the file and restart Grafana instead. If you'd rather add it by hand, the same page describes Connections → Add new connection → Prometheus → Add new data source.
Check the files, then start
Both images include their own config checkers, so you can test the files before anything runs. From the monitoring directory:
docker run --rm --entrypoint promtool \
  -v "$PWD/prometheus.yml:/etc/prometheus/prometheus.yml:ro" \
  -v "$PWD/alert_rules.yml:/etc/prometheus/alert_rules.yml:ro" \
  prom/prometheus:v3.15.0 check config /etc/prometheus/prometheus.yml

docker run --rm --entrypoint amtool \
  -v "$PWD/alertmanager.yml:/etc/alertmanager/alertmanager.yml:ro" \
  prom/alertmanager:v0.34.1 check-config /etc/alertmanager/alertmanager.yml
promtool should report SUCCESS for the config and 4 rules found for the rule file; amtool should end with SUCCESS and list one receiver. Resolve any errors from your pinned tool versions before you continue. Check that the host or cloud firewall restricts node_exporter port 9100, then start the stack and check each piece:
docker compose up -d
docker compose ps                              # five services, all running
curl -s http://127.0.0.1:9090/-/ready          # Prometheus Server is Ready.
curl -s http://127.0.0.1:9093/-/ready          # OK
curl -s http://127.0.0.1:3000/api/health       # "database": "ok"
To open Grafana, Prometheus and Alertmanager from your own computer, tunnel them over SSH. Browse to http://localhost:3000, http://localhost:9090/targets and http://localhost:9093, respectively:
ssh -N -L 3000:127.0.0.1:3000 -L 9090:127.0.0.1:9090 -L 9093:127.0.0.1:9093 you@your-serverThe targets page should show the prometheus, node and cadvisor jobs as UP, and /alerts should list the four rules as inactive.
If the node target is DOWN on a ufw host
node_exporter listens on the host network, so unlike published container ports, it is covered by ufw. With ufw's default deny for incoming traffic, that also blocks Prometheus, whose requests arrive from the Compose network. Allow that subnet only:
SUBNET=$(docker network inspect monitoring_default --format '{{(index .IPAM.Config 0).Subnet}}')
sudo ufw allow from "$SUBNET" to any port 9100 proto tcp
Port 9100 stays closed to the rest of your network.
Dashboards
With the SSH tunnel open, log in to Grafana at http://localhost:3000 as admin with the password from .env. Then import a ready-made dashboard as described in Grafana's import docs:
- Click Dashboards, then New → Import dashboard.
- Enter
1860, the ID of Node Exporter Full, and click Load. - Select the Prometheus data source and click Import.
For container panels, search grafana.com for a dashboard built for cAdvisor metrics, and prefer one that has been updated recently. Imported dashboards are stored in Grafana's database, so they're covered by the Grafana backup below.
Test the alert path on purpose
An alerting setup you haven't seen deliver a message is a guess. Test the two halves separately. First Alertmanager to Telegram or email, with a synthetic alert:
docker compose exec alertmanager amtool alert add TestAlert severity=warning \
  --annotation=summary='Test from amtool' --alertmanager.url=http://localhost:9093
The message should arrive after the 30-second group_wait. Then the full chain from Prometheus, by stopping an exporter:
docker compose stop node_exporter
# after about 2 minutes: InstanceDown is "firing" on /alerts and a message arrives
docker compose start node_exporter
# a resolved message follows (Telegram, or email with send_resolved: true)
PromQL you'll actually use
# CPU busy, percent per host
100 - (avg by (instance) (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100)

# Memory in use, percent
(1 - (node_memory_MemAvailable_bytes / node_memory_MemTotal_bytes)) * 100

# Disk used, percent, without RAM disks and container layers
(1 - (node_filesystem_avail_bytes{fstype!~"tmpfs|overlay"} / node_filesystem_size_bytes{fstype!~"tmpfs|overlay"})) * 100

# CPU per container from cAdvisor, in cores
sum by (name) (rate(container_cpu_usage_seconds_total{name!=""}[5m]))

# Which targets are down
up == 0
Run them on the Prometheus query page or in Grafana's Explore view. rate() turns an ever-growing counter into a per-second rate over the window in brackets.
Retention, disk space and backups
Without retention flags Prometheus keeps 15 days. The Compose file sets 30 days and a 10 GB cap; whichever limit is reached first applies. The storage docs recommend keeping the size limit at no more than 80–85% of the space you give Prometheus, because compaction briefly needs room for old and new blocks at the same time, and they give a sizing formula: retention in seconds × samples ingested per second × 1–2 bytes. As a worked example, 5,000 series scraped every 15 seconds is about 333 samples per second; over 30 days (2,592,000 seconds) at 2 bytes per sample that comes to roughly 1.7 GB. The query prometheus_tsdb_head_series shows how many series your own setup has. Expired blocks can take up to two hours to disappear. For months or years of history, look at remote storage such as Thanos or Mimir instead of a huge local volume.
What to back up
- The project directory. The YAML files are the whole configuration. Keep them in Git and back up
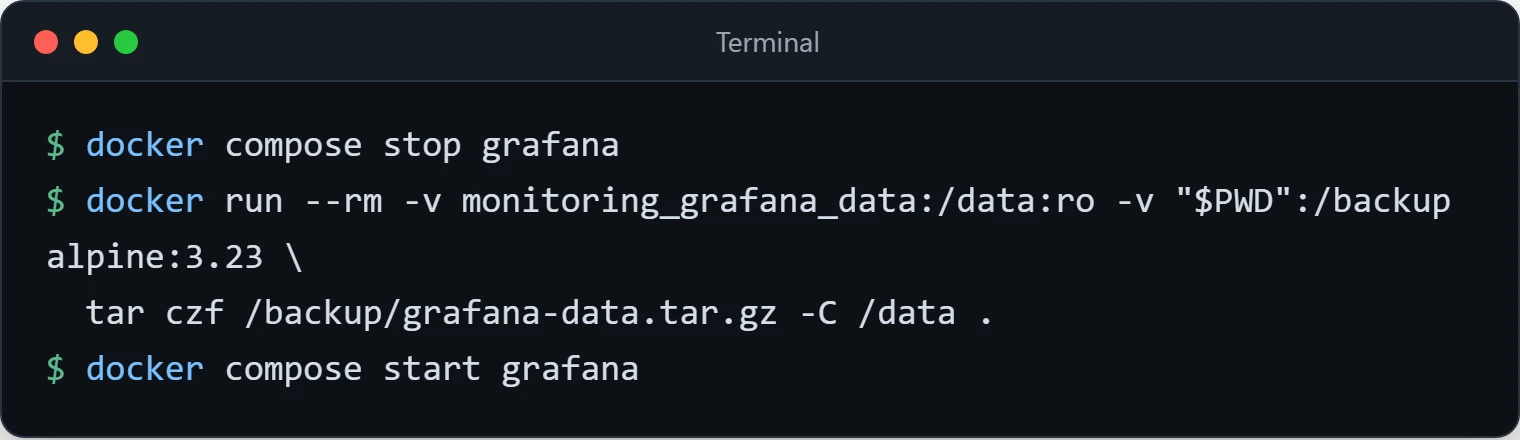
.envandsecrets/separately. - Grafana's volume, which holds imported dashboards, users and settings in a SQLite database. Stop Grafana so the copy is consistent:
docker compose stop grafana
docker run --rm -v monitoring_grafana_data:/data:ro -v "$PWD":/backup alpine:3.23 \
  tar czf /backup/grafana-data.tar.gz -C /data .
docker compose start grafana- Prometheus data, only if the history matters to you. The storage docs recommend TSDB snapshots for backups, which need the admin API. That API can also delete data, so enable it only while you take the snapshot. Add
- --web.enable-admin-apito theprometheuscommand list, rundocker compose up -d prometheus, then:
curl -s -XPOST http://127.0.0.1:9090/api/v1/admin/tsdb/snapshot
docker compose cp prometheus:/prometheus/snapshots ./prometheus-snapshots
docker compose exec prometheus rm -rf /prometheus/snapshots
The snapshot is written inside the data volume, so the last command removes it there once you have a copy. Remove the flag again and run docker compose up -d prometheus. Copy the backups off the server; the self-hosting guide's backup section covers restic and off-site copies.
Monitoring more machines
Run node_exporter on each extra Linux host, either with the same Compose service or from your distribution's packages, and add it to the node job:
  - job_name: 'node'
    static_configs:
      - targets: ['host.docker.internal:9100', '192.168.1.20:9100', '192.168.1.21:9100']
On those hosts, allow port 9100 only from the monitoring server's address. Check the file with promtool again, then docker compose restart prometheus to load it. For "is the website actually answering?" checks from the outside, add blackbox_exporter, which probes HTTP, DNS and TCP endpoints.
Upgrading
Read the release notes for each image you're changing, edit the tags in compose.yaml, back up Grafana's volume, and run:
docker compose pull
docker compose up -d
docker compose ps
Change one component at a time so you know which one to roll back. Rolling back means putting the old tag back and running docker compose up -d; for Grafana, restore the volume backup too if the new version migrated its database.
Troubleshooting
nodetarget is DOWN with "connection refused" or a timeout. On the host,curl -s http://127.0.0.1:9100/metrics | headshould print metrics. Then test from Prometheus:docker compose exec prometheus wget -qO- http://host.docker.internal:9100/metrics | head. If the first works and the second doesn't, a host firewall is in the way; see the ufw rule above.cadvisoris DOWN or keeps restarting. Readdocker compose logs cadvisor. The cAdvisor README points users of Fedora, RHEL, CentOS and LXC to its separate running instructions for extra flags.- Prometheus won't start or ignores an edit. Run the promtool check from above and read
docker compose logs prometheus. Prometheus reads its config at startup, so restart it after editing. - The Grafana password from
.envdoesn't work. It's only applied when Grafana first creates its database. Reset it withdocker compose exec grafana grafana cli admin reset-admin-password 'new-password', as described in the Grafana CLI docs. - Alerts fire but no message arrives. The amtool test above tells you whether the problem is in Alertmanager or before it.
docker compose logs alertmanagershows errors from Telegram or the mail server; a wrongchat_id, a revoked token or a token file thenobodyuser can't read are the usual causes. - Disk alerts for filesystems you don't care about. Add them to the
fstype!~filter or add amountpoint!~filter to the rule.
Removing the stack
docker compose down stops and removes the containers but keeps the volumes, so a later up -d brings the history back. docker compose down -v also deletes the three volumes, including every metric and Grafana dashboard, so take the backups above first. Remove the ufw rule afterwards with sudo ufw status numbered and sudo ufw delete NUMBER.
Where to go next
- Grafana Loki Deployment adds logs to the same Grafana, with Grafana Alloy as the collector, and its ruler can send alerts to this Alertmanager.
- Nginx Web Server Setup puts Grafana behind HTTPS.
- The Complete Self-Hosting Guide for 2026 covers backups, updates and remote access for the rest of the server.